
Make a tiny version of yourself
Choose a clear photo of one person. The model uses the visible face, hairstyle and outfit to guide a doll-sized character, with exaggerated miniature proportions and expressions.
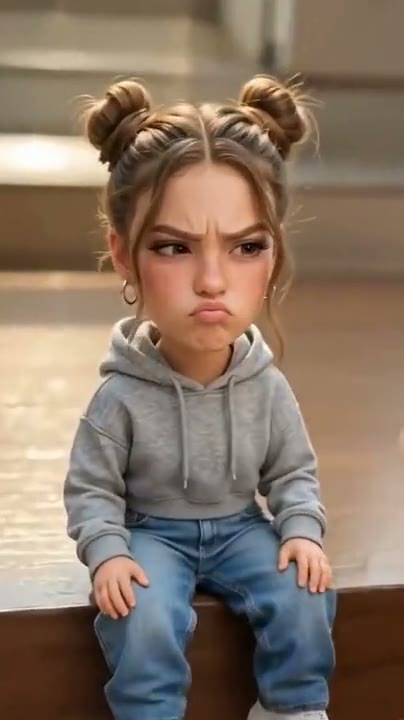
Turn one photo into a tiny you on a window ledge. A giant hand offers your mini me an ice-cream cone in this five-second scene.
Mini Me AI turns one person’s photo into a stylized miniature character. In this version, the tiny person sits on a window ledge, reacts to a giant hand and takes an ice-cream cone. The prepared five-second clip supplies the hand, setting and sequence.
Add one photo, review the prepared scene and generate.
STEP 1
A clear photo of one person, with their face, hair and intended outfit visible.
STEP 2
The preview shows the fixed action and setting. Choose an available mode and review the displayed credit estimate.
STEP 3
Start the generation, then open My creations to watch and download the result.
Explore a third-party example of this scene. Your result can look different.
Choose a clear photo of one person. The model uses the visible face, hairstyle and outfit to guide a doll-sized character, with exaggerated miniature proportions and expressions.
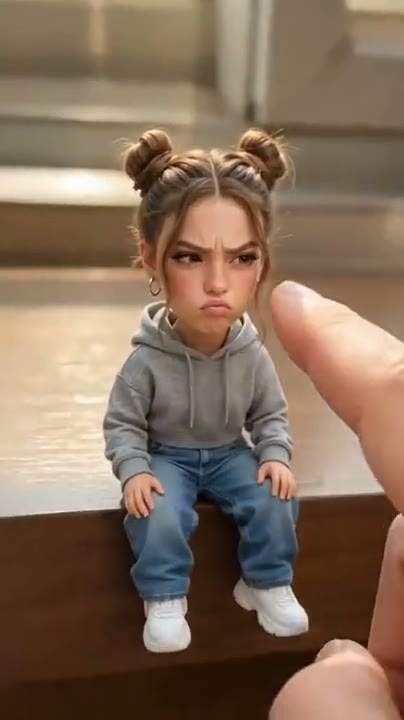
The miniature character begins with a pout, notices a cone offered by the giant hand, then reaches for it and takes a bite. The reference guides those gestures and expressions; details can vary in a generated result.
The window ledge, close-up framing and large hand create the size contrast. This template focuses on a single miniature person; it does not add a full-size version of you in the same scene.
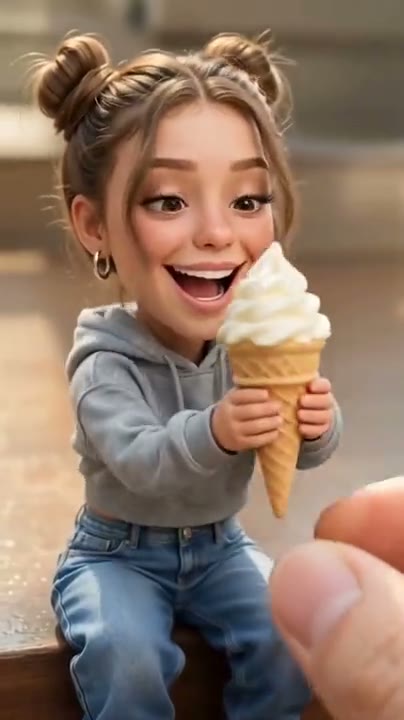
Your photo guides the assigned role; the prepared video supplies the rest of the scene.
A clear photo of one person, with their face, hair and intended outfit visible.
The prepared five-second clip supplies the hand, setting and sequence.
Available modes and the estimated credit cost appear in the workspace before generation.
Photos, the ice-cream scene, sound and settings.
No. This version shows one miniature person interacting with a large hand. It does not add a separate full-size version.
The template uses the prepared reference audio. It has no field for a voice recording or custom dialogue.
The prepared reference is five seconds long and covers the reaction, ice cream and smile.
The cone and window-ledge setting are part of the fixed scene. There is no separate food or location selector.
One photo is required for the mini me.
A clear photo of one person, with their face, hair and intended outfit visible.
This is a fixed scene. The uploaded photo guides the specified role while the reference supplies the action and setting.
The template uses the prepared reference audio when that mode supports restoring it. Check the available settings before generating.
The model uses the photo as an appearance reference. Facial details, clothing and movement can vary between generated results.
The workspace shows the estimated credits for the selected mode and settings before you generate.